帖子 · @bebuu_ai
详细解读
收录时间: · 发布时间:
永久链接解读
此帖暂无已保存的解读。
原始内容
South Korea's LG AI Research just entered the big MoE weight class today (November 9) by opening a free API beta for K-EXAONE 2.5 and they benchmarked it directly against DeepSeek V4.1 Flash and Zhipu's GLM 5.3.
Here are the specs they just revealed:
- Size: 750 billion total parameters with 31 billion active per token (750B-A31B MoE).
- Context: 512K tokens using hybrid attention plus Multi-Token Prediction (MTP).
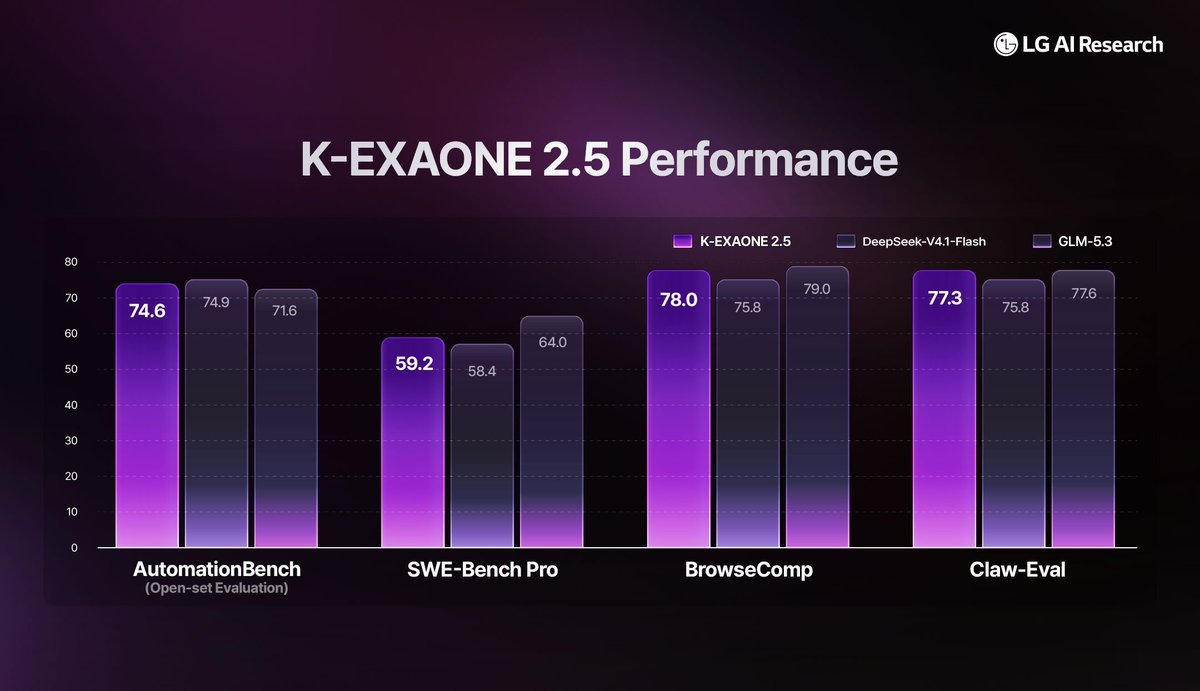
On their published agentic benchmarks:
- SWE-Bench Pro: Zhipu's GLM-5.3 still holds #1 in this group at 64.0%, but K-EXAONE 2.5 hits 59.2%, edging past DeepSeek-V4.1-Flash (58.4%).
- BrowseComp & Claw-Eval: K-EXAONE 2.5 scores 78.0 and 77.3, beating DeepSeek-V4.1-Flash (75.8 on both) and landing within a point of GLM-5.3.
Developers in China are already grabbing the free API keys on https://t.co/5UhQAR5a72 to wire it into their coding harnesses, though early testers warn it's tuned for English and Korean rather than Chinese.
已保存译文 · zh-cn
韩国的 LG AI Research 今天(11月9日)通过为 K-EXAONE 2.5 开启免费 API beta 测试,正式进入了 MoE 权重级别,并且他们将其直接与 DeepSeek V4.1 Flash 和 智谱的 GLM 5.3 进行了基准测试。
以下是他们刚刚公布的规格:
- 规模:总参数 7500 亿,每个 token 激活 310 亿(750B-A31B MoE)。
- 上下文:使用混合注意力机制(hybrid attention)加上多 Token 预测(MTP),支持 512K token。
在他们公布的智能体基准测试中:
- SWE-Bench Pro:智谱的 GLM-5.3 在该组中仍以 64.0% 占据第 1 位,但 K-EXAONE 2.5 达到了 59.2%,略高于 DeepSeek-V4.1-Flash (58.4%)。
- BrowseComp & Claw-Eval:K-EXAONE 2.5 得分为 78.0 和 77.3,击败了 DeepSeek-V4.1-Flash(两者均为 75.8),并与 GLM-5.3 的差距在 1 分之内。
中国的开发者已经在 https://t.co/5UhQAR5a72 抢夺免费 API 密钥,将其接入他们的代码框架,不过早期测试者警告称,它针对英语和韩语进行了优化,而非中文。